How to Fix an AI That Starts Hallucinating in Long Chats
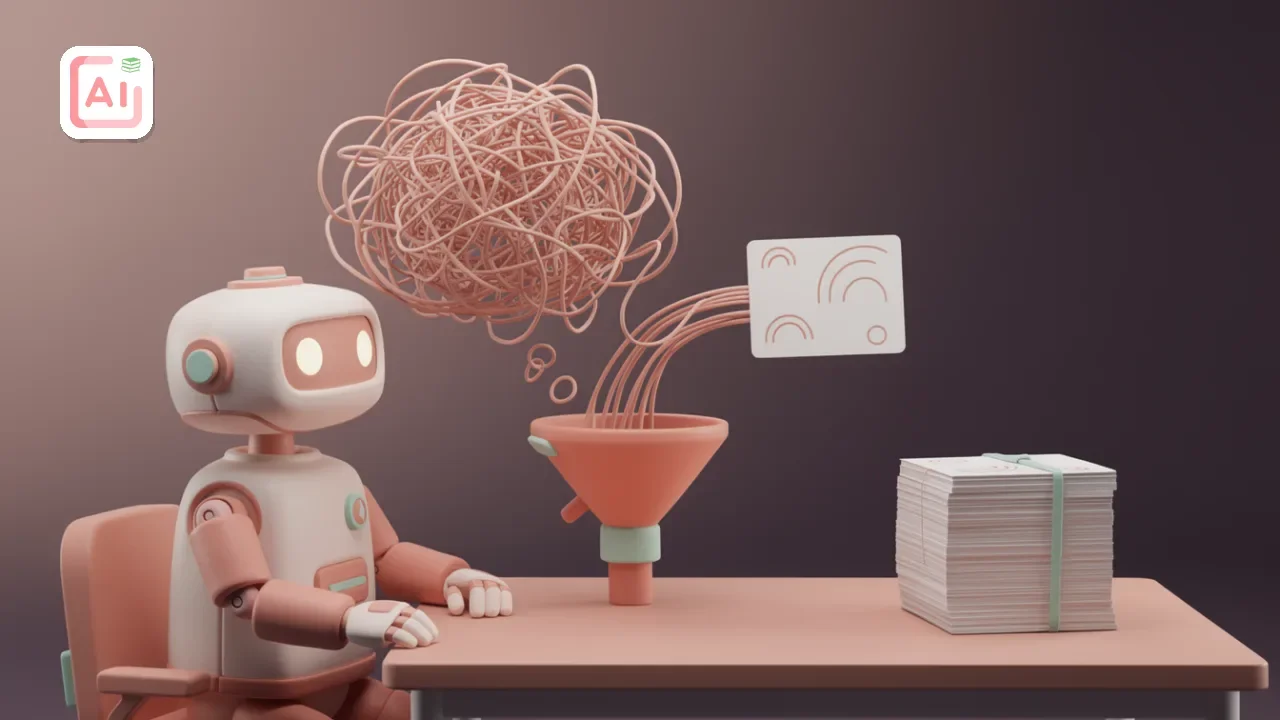
Table of Contents
You have probably noticed this: at the beginning of work on a new task, ChatGPT, Claude, or another language model provides ideal, accurate answers. But once the conversation grows to dozens of messages, the AI starts repeating itself, forgetting previous requirements, hallucinating, or openly contradicting itself.
This is not a bug in a specific model and does not mean that the service has “gone downhill.” It is a fundamental limitation of modern architectures — context-window overflow and noise.
💡 The main principle of working with context:
A neural network’s context window is RAM (random-access memory), not a hard drive. If RAM is filled with junk, the system starts to “slow down.” Anything that is not currently needed should be moved to external memory.
Why the dialogue “gets dumber”: Physics of Context Rot
Even if developers claim support for 128k or 1M tokens, information-processing quality is not uniform across the entire context length. Three fundamental phenomena are responsible:
- Needle in a Haystack: The more text is provided as input (Prompt), the lower the probability that the Attention Mechanism will correctly extract a single key fact from the middle of the context.
- Lost in the Middle: Research shows that LLMs analyze the beginning (System Prompt / initial requirement) and the very end of a dialogue most effectively. Instructions “buried” in the middle of the message history lose priority.
- Context Rot (Context degradation): Accumulated noise (failed generations, intermediate clarifications, polite phrases) disrupts the focus of attention. The model starts relying on its own erroneous answers, creating a “hallucination loop.”
Technique 1: Compaction (Context Compression)
When you feel that the dialogue has grown too long and the model is starting to lose the thread — do not keep arguing or pushing in the same chat. This is the worst strategy, as it only increases the amount of noise.
Use the Compaction method: ask the model to compress the essence of the current state, then transfer that summary to a completely clean dialogue.
Ready-to-use prompt for compression:
Summarize our dialogue:
1. The key decisions we made and why we made them.
2. The current state of the task.
3. Important technical constraints and details.
4. What exactly we are doing next.

Format: a concise structured list. I will continue working from this summary in a new chat.
Action algorithm:
- Send the prompt in the “old,” bloated chat.
- Copy the resulting summary (Summary).
- Create a completely new chat (New Chat).
- Paste the summary as the first message and continue working. The model will once again operate with 100% accuracy and “sharp” attention.
Technique 2: Memory in a File (Structured Note-Taking)
For long-term projects spanning days or weeks, the Compaction method alone is not enough. This is where the Structured Note-Taking pattern — maintaining an external memory file — is used.
You create a regular text file (project_context.md or .txt), store it locally, and upload it at the beginning of a new AI session whenever necessary. This is not an archive of the entire conversation. It is a short, owner-editable source of truth: what we are doing, which decisions are currently active, and what cannot be changed without separate approval.
What to include in the project memory file:
- Context and goals: Project description, technology stack, target audience.
- Architectural decisions: What was chosen and why alternatives were rejected (so the AI does not suggest them again).
- Rules and guidelines: Code requirements, text style, format constraints.
- Current State: What has already been done and what the next step is.
For a content website, this file can contain the section structure, internal-linking rules, selected URLs, translation requirements, the adopted stack, and a list of ideas that have already been rejected. For development, it can include architectural decisions, verification commands, environment constraints, and the status of the current stage.
What to store in PROJECT_CONTEXT.md
# Project context

Updated: YYYY-MM-DD

## Goal
- The result that must be achieved.

## Current state
- What has already been done.
- What is currently working.

## Active decisions
- Decision — why it was made.
- Decision — why it was made.

## Requirements
- Required format.
- Technical and editorial constraints.
- Language, style, audience.

## Rejected options
- Option — why it was rejected.

## Exact data
- URLs, names, versions, numbers, and other values that must not be distorted.

## Open questions and risks
- What has not yet been verified or still requires a decision.

## Next action
- One specific immediate next step.

## Change log
- YYYY-MM-DD — what changed and why.
How to maintain the memory file
- Keep it short: 50 up-to-date lines are usually more useful than 500 lines of history.
- Record decisions, not the entire course of the discussion.
- Delete outdated information or clearly mark it as obsolete.
- Preserve the reasons behind important decisions so the model does not suggest reversing them without new grounds.
- After a significant stage, ask the model to suggest an update to the file, but review the changes yourself.
- Do not store passwords, API keys, private client data, or other sensitive information in it.
Comparing the approaches
| Method | When to use it | Main advantage |
|---|---|---|
| Compaction | Within a single work session, when the chat exceeds ~15–20 messages. | Instantly clears the attention window without losing current progress. |
| Memory in a file | For long-term development, documentation writing, and cross-functional projects. | Complete independence from chat history and a fast start in any LLM. |
Conclusion
For effective work with LLMs, maintain a short project memory file and periodically perform Compaction within active sessions. This will save you time and eliminate the need to explain the same thing ten times.
I study AI not as magic but as a tool. I love order in data and complex systems.